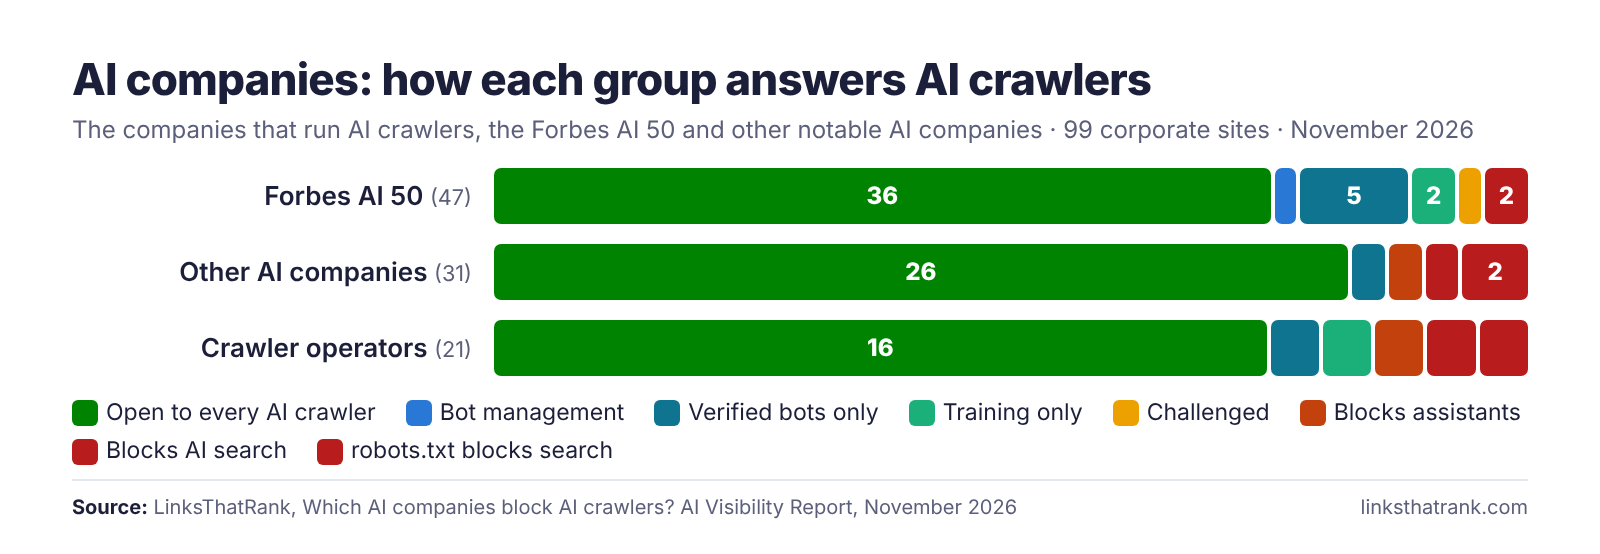
We tested 115 websites of 99 AI companies as 33 different AI crawlers. Seven of the 21 companies that run a crawler of their own - OpenAI, Anthropic, Microsoft, Meta, Amazon, Perplexity and Mistral AI - block a rival’s crawler by name. The other fourteen operators, Google and Apple among them, block nobody, and 78 of the 99 corporate sites admit every crawler tested.
By Matthew Woodward, LinksThatRank · Published 12 November 2026 · Data collected 6–7 November 2026 · Re-run quarterly, next update February 2027
Copy any line with the source attached - free to use with credit.
ChatGPT’s website blocks Perplexity. Claude’s blocks ChatGPT. Perplexity’s blocks both.Three companies, three rules that name each other’s crawlers - each reproducible with one curl command.
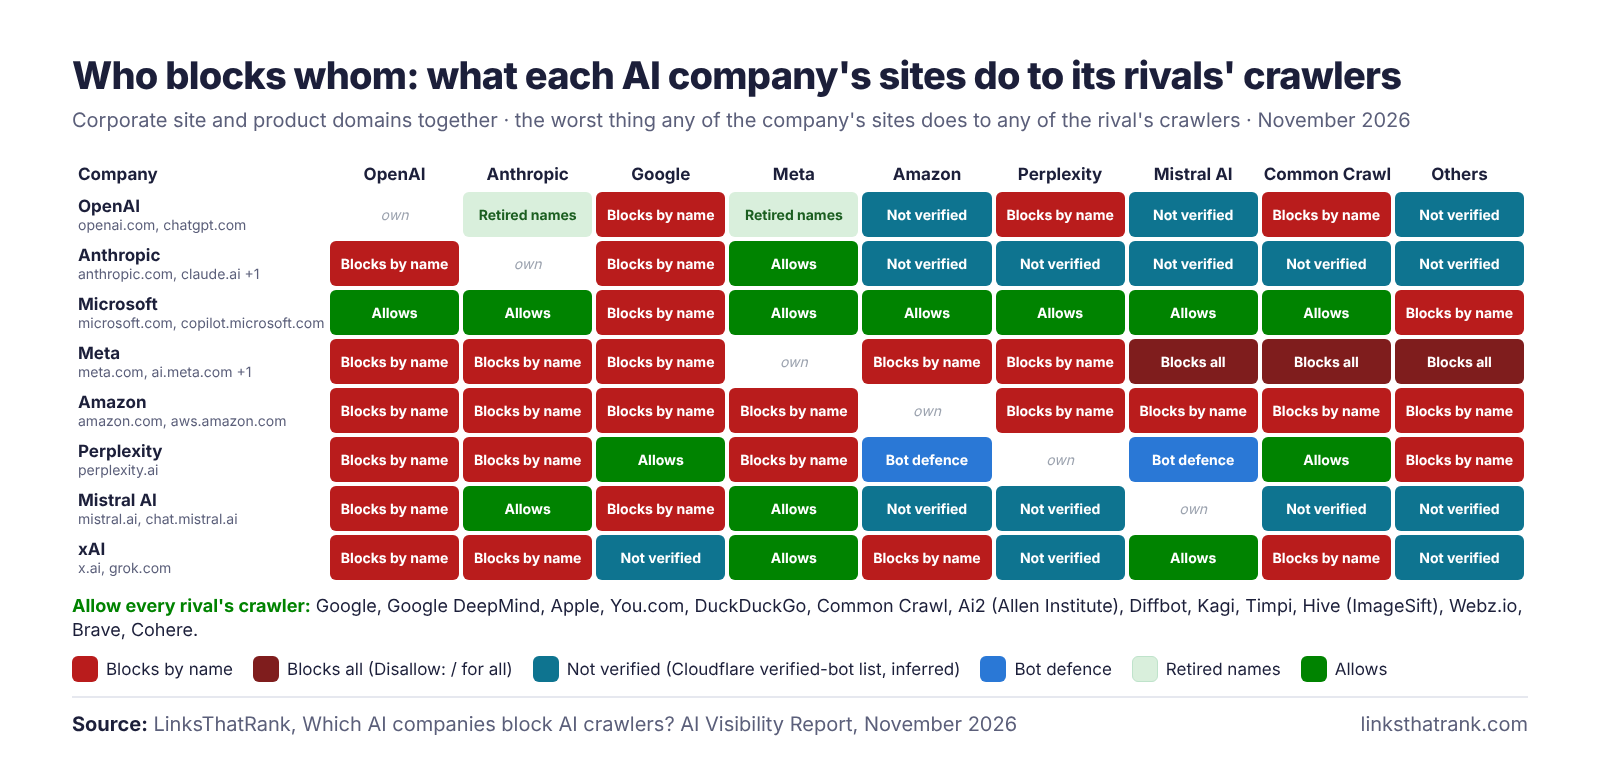
7 of the 21 companies that run an AI crawler block a rival’s crawler by name: OpenAI, Anthropic, Microsoft, Meta, Amazon, Perplexity and Mistral AI.The companies whose products depend on an open web are the ones closing it to each other.
claude.ai blocks OpenAI’s crawlers in robots.txt. chatgpt.com blocks Perplexity’s in robots.txt. perplexity.ai blocks OpenAI’s and Anthropic’s at the edge.A circular firing squad - and every rule is reproducible with a single curl command.
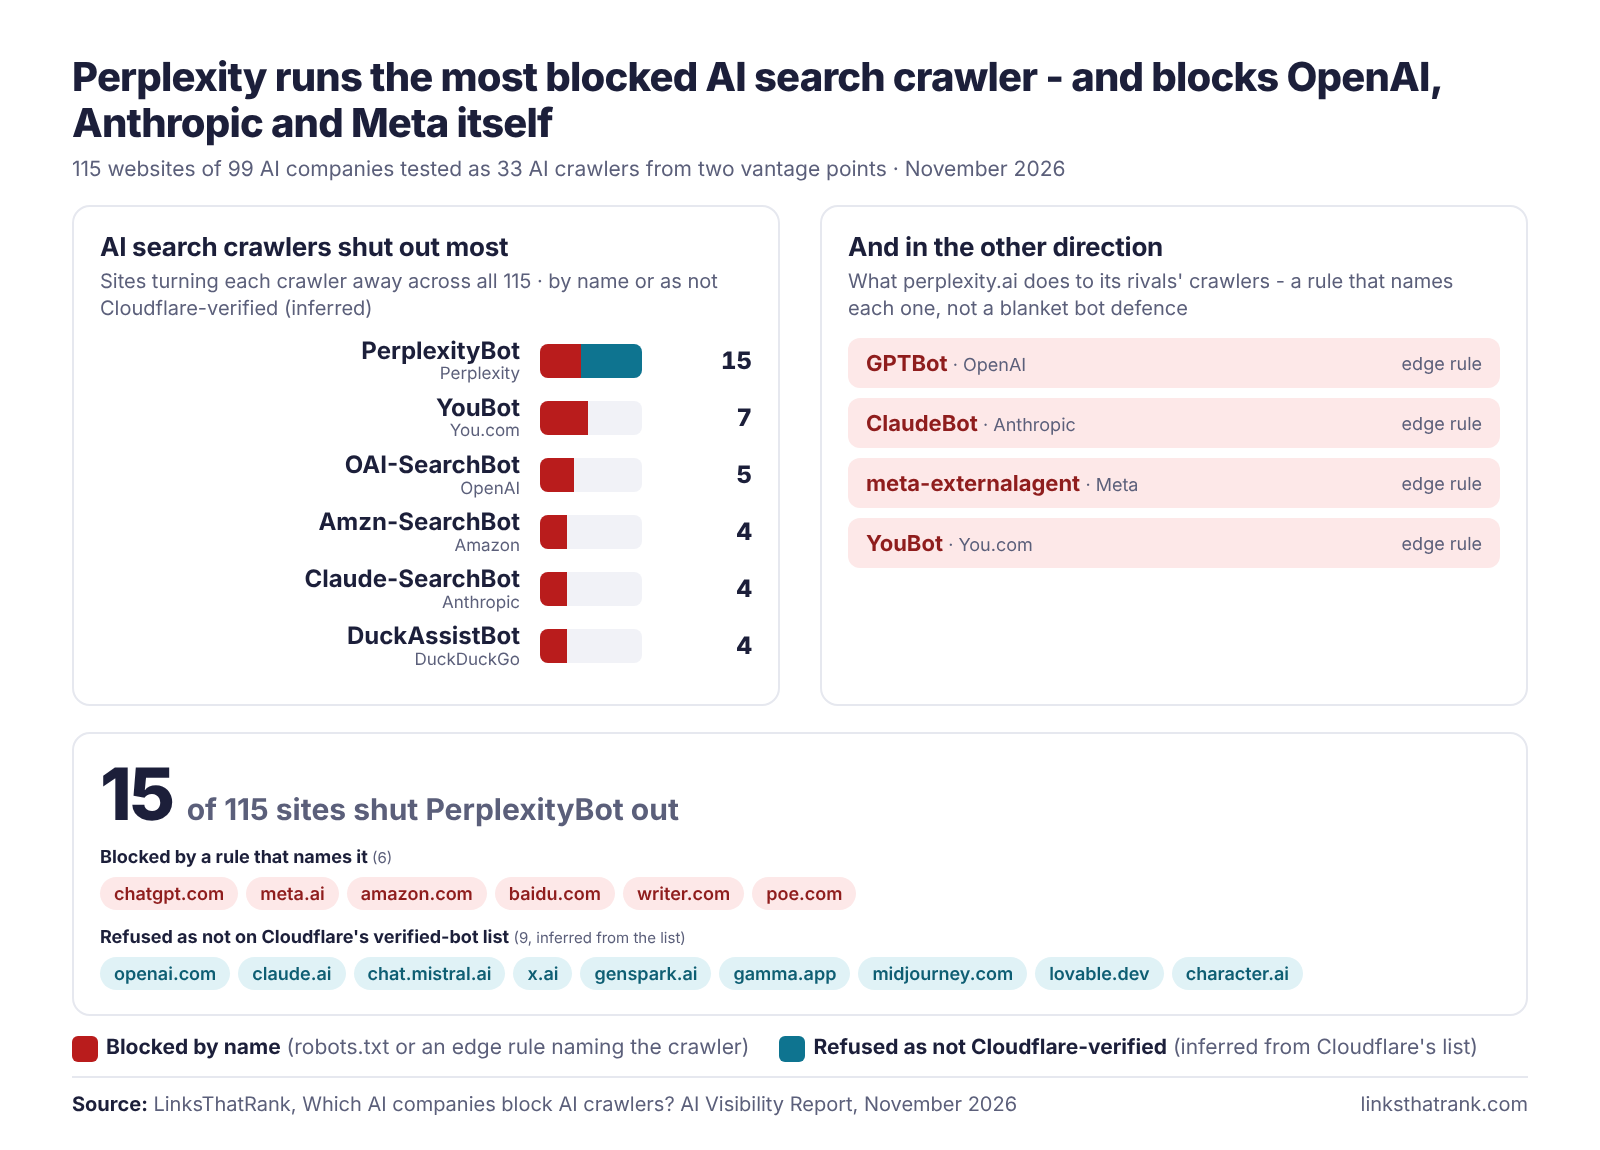
PerplexityBot is shut out of 15 of the 115 AI-company sites tested - more than any other AI search crawler.The industry’s most blocked search crawler belongs to one of its loudest search players.
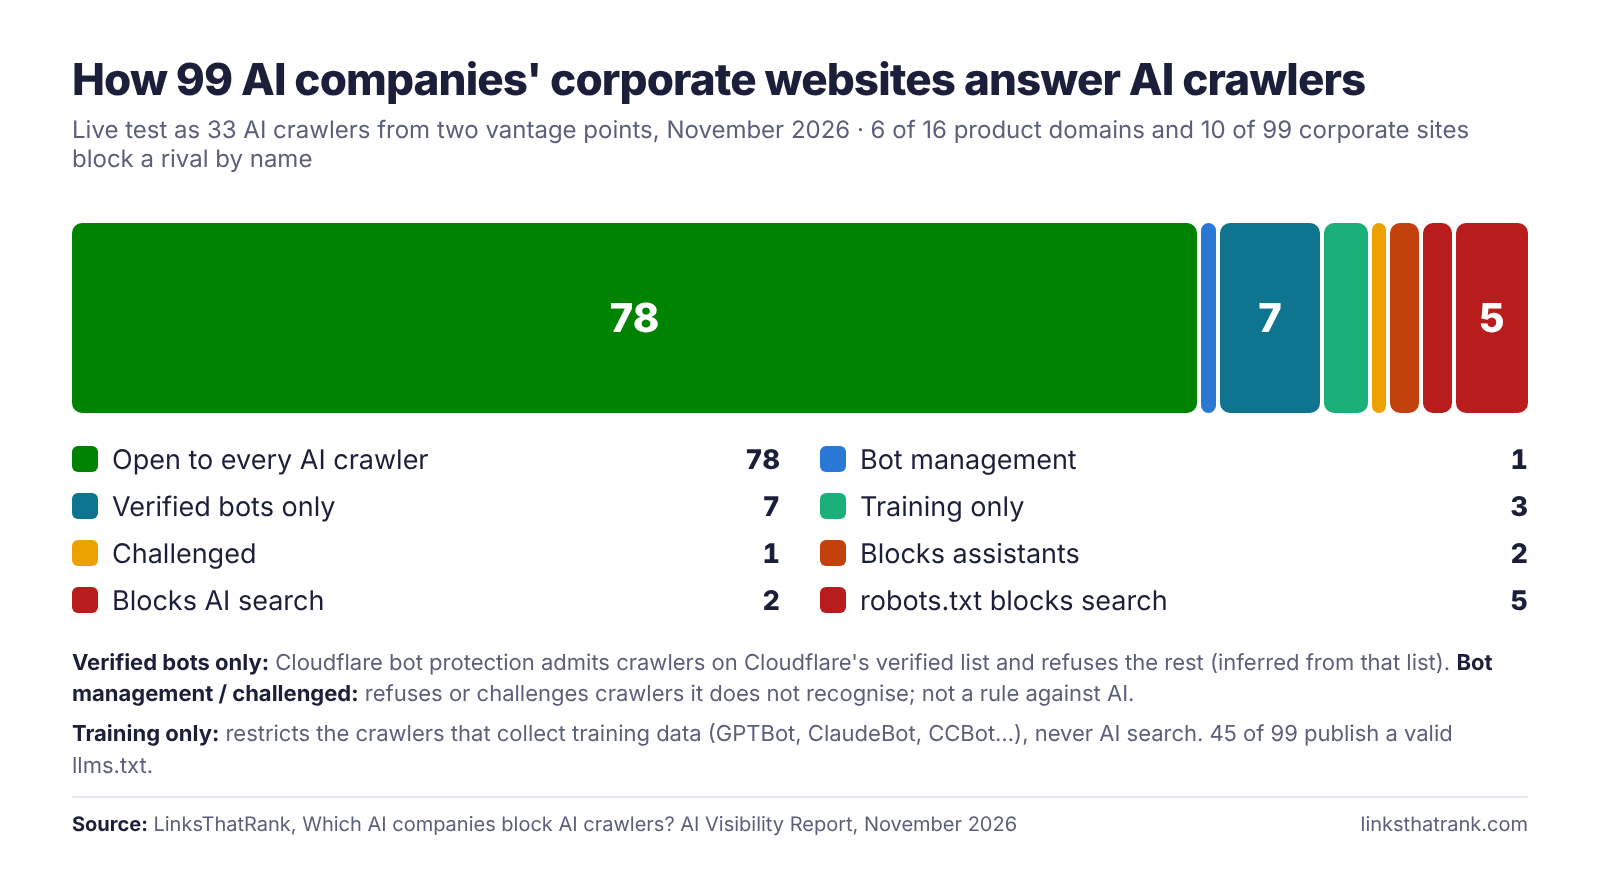
78 of the 99 AI companies’ corporate websites admit every one of the 33 AI crawlers tested.The blocking is concentrated at the top of the industry, not spread across it.
45 of the 99 AI companies publish a valid llms.txt. None of the eight largest - OpenAI, Anthropic, Google, Microsoft, Meta, Amazon, Apple and Perplexity - does.The machine-readability standard the ecosystem promotes has zero adoption among its biggest names.
11 of the 115 sites admit only crawlers on Cloudflare’s verified-bot list.A vendor’s list, not company policy, decides which AI crawlers can read the AI industry’s own sites.
The story in six findings
The AI industry is open to AI crawlers - except to each other’s.
Six numbers carry the report: who blocks a rival, whose crawler gets blocked most, how open the industry is, where the strictness lives, who adopts llms.txt, and who controls the gate.
7/ 21
crawler operators block a rival’s crawler by name
OpenAI, Anthropic, Microsoft, Meta, Amazon, Perplexity and Mistral AI each shut at least one rival out in robots.txt or at the edge. Fourteen operators, Google and Apple among them, block nobody.
Why it mattersThe crawler wars are between the household names, not the long tail.
15/ 115
sites shut PerplexityBot out - the most of any AI search crawler
Six block it by name, including chatgpt.com, meta.ai and amazon.com. Nine more refuse it because Cloudflare’s verified-bot list does not include it.
Why it mattersThe most blocked AI search crawler belongs to an AI search company.
78/ 99
corporate sites are open to every AI crawler tested
9 sit behind bot defences, 3 restrict training crawlers only, and 9 name an AI search or assistant crawler in a block rule.
Why it mattersThe blocking is concentrated at the top of the industry, not spread across it.
6/ 16
product domains block a rival’s crawler by name
chatgpt.com, claude.ai, ai.meta.com, meta.ai, chat.mistral.ai and grok.com - against 10 of the 99 corporate sites.
Why it mattersThe marketing site stays open; the app that holds the conversations does not.
45/ 99
publish a valid llms.txt
None of the eight largest AI companies does, and 9 more answer the URL with something that is not an llms.txt.
Why it mattersThe standard the ecosystem promotes has zero adoption among its biggest names.
11/ 115
sites admit only crawlers on Cloudflare’s verified-bot list
The gatekeeper for Google-GeminiNotebook, Perplexity-User, PerplexityBot and every other crawler not on it (inferred from the list).
Why it mattersA vendor’s list, not company policy, decides which AI crawlers get in.
1
Who blocks whom
Seven AI giants block a rival’s crawler by name. Fourteen operators block nobody.
The matrix below shows what each company’s websites do to its rivals’ crawlers, corporate site and product domains together (chatgpt.com with openai.com, claude.ai with anthropic.com). A cell shows the worst thing any of the company’s sites does to any of that rival’s crawlers. Count xAI, whose crawler is not in the registry this test sends, and it is 8 of the 22 companies in the matrix.
The eight that block Each row is one company’s sites; each column is one rival operator’s crawlers · November 2026
Blocks by nameBlocks by name robots.txt or an edge rule naming the crawlerBlocks allBlocks all Disallow: / for every user agentNot verifiedNot verified refused by Cloudflare bot protection, not on its verified-bot list (inferred)Bot defenceBot defence challenge or bot management, no rule naming the crawlerRetired namesRetired names rules for old crawler names; the live crawler gets in
Hover a cell for the crawlers behind it.
The other 14 operators allow every rival crawler tested:GoogleGoogle DeepMindAppleYou.comDuckDuckGoCommon CrawlAi2 (Allen Institute)DiffbotKagiTimpiHive (ImageSift)Webz.ioBraveCohere
Right-click to save and reuse with credit - the source line is part of the image.
The rules, line by lineEvery block rule quoted, with the one-command evidence - for the technically minded
Each block is a rule that names the crawler - not a blanket bot defence. Open any rule for the exact commands; the company table carries the per-crawler verdicts for all 115 sites.
OpenAI → Google, Perplexity and Common Crawlchatgpt.com’s robots.txt disallows Google-Extended, PerplexityBot and CCBot. Its rules for the retired names anthropic-ai, Claude-Web, Omgilibot, Omgili and FacebookBot match nothing.Show evidence (2 commands)
PerplexityBot disallowed (line 40: Disallow: /):
curl -s 'https://chatgpt.com/robots.txt' | sed -n '39,40p'
CCBot disallowed (line 4: Disallow: /):
curl -s 'https://chatgpt.com/robots.txt' | sed -n '3,4p'
Anthropic → OpenAI and Googleclaude.ai’s robots.txt disallows OAI-SearchBot, ChatGPT-User, GPTBot and Google-Extended.Show evidence (1 command)
OAI-SearchBot, ChatGPT-User and GPTBot disallowed (line 10: Disallow: /):
curl -s 'https://claude.ai/robots.txt' | sed -n '6,10p'
Microsoft → Google and Webz.ioAn edge rule on microsoft.com refuses GoogleOther and webzio - every one of those names gets the edge’s block response.Show evidence (2 commands)
webzio served a different page instead of the site (HTTP 200) - the command prints its title, expect “Your request has been blocked. This could be due to several reasons.” (a browser gets “Microsoft: IA, nube, productividad, informática, juegos y aplicaciones”): Akamai also judges the client, so plain curl can get this page for every user agent from some networks; the clean reproduction is a browser - Chrome DevTools → Network conditions → User agent User agent → paste the agent above and load the page.rarr; paste the user agent from the command and load the page.
curl -s -A 'webzio' 'https://www.microsoft.com/es-es' | grep -o '<title>[^<]*'
GoogleOther served a different page instead of the site (HTTP 200) - the command prints its title, expect “Your request has been blocked. This could be due to several reasons.” (a browser gets “Microsoft: IA, nube, productividad, informática, juegos y aplicaciones”): Akamai also judges the client, so plain curl can get this page for every user agent from some networks; the clean reproduction is a browser - Chrome DevTools → Network conditions → User agent User agent → paste the agent above and load the page.rarr; paste the user agent from the command and load the page.
curl -s -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GoogleOther) Chrome/W.X.Y.Z Safari/537.36' 'https://www.microsoft.com/es-es' | grep -o '<title>[^<]*'
Meta → OpenAI, Anthropic, Google, Amazon, Apple and Perplexitymeta.ai’s robots.txt disallows GPTBot, ClaudeBot, Google-Extended, Amazonbot, Applebot-Extended and PerplexityBot - then Disallow: / for everyone else, Meta’s own crawlers included. An edge rule on meta.com and ai.meta.com refuses Google-GeminiNotebook.Show evidence (3 commands)
PerplexityBot disallowed (line 22: Disallow: /):
curl -s 'https://meta.ai/robots.txt' | sed -n '8,22p'
The catch-all group - Disallow: / for every other user agent (line 52: Disallow: /):
curl -s 'https://meta.ai/robots.txt' | sed -n '51,52p'
Google-GeminiNotebook refused by the edge rule - expect HTTP 400:
curl -sSI -A 'Mozilla/5.0 (X11; Linux x86_64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/137.0.0.0 Safari/537.36 (compatible; Google-GeminiNotebook; +https://developers.google.com/crawling/docs/crawlers-fetchers/google-gemininotebook)' 'https://www.meta.com/gb/'
Amazon → 14 operatorsamazon.com’s robots.txt disallows OAI-SearchBot, ChatGPT-User, GPTBot, Claude-SearchBot, Claude-User, ClaudeBot, Google-CloudVertexBot, GoogleOther and 14 more. Its rules for the retired names omgili and Claude-Web match nothing.Show evidence (3 commands)
OAI-SearchBot disallowed (line 277: Disallow: /):
curl -s 'https://amazon.com/robots.txt' | sed -n '276,277p'
curl -s 'https://amazon.com/robots.txt' | sed -n '252,253p'
PerplexityBot disallowed (line 151: Disallow: /):
curl -s 'https://amazon.com/robots.txt' | sed -n '150,151p'
Perplexity → OpenAI, Anthropic, Meta and You.comAn edge rule on perplexity.ai refuses GPTBot, ClaudeBot, meta-externalagent and YouBot - every one of those names gets the edge’s block response.Show evidence (3 commands)
YouBot refused by the edge rule - expect HTTP 403:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; YouBot/1.0; +https://docs.you.com/youbot; env:prod) Chrome/X.X.X.X Safari/537.36' 'https://www.perplexity.ai/'
GPTBot refused by the edge rule - expect HTTP 403:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot' 'https://www.perplexity.ai/'
ClaudeBot refused by the edge rule - expect HTTP 403:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; ClaudeBot/1.0; [email protected])' 'https://www.perplexity.ai/'
Mistral AI → OpenAI and Googlechat.mistral.ai’s robots.txt disallows GPTBot and Google-Extended.Show evidence (1 command)
GPTBot disallowed (line 2: Disallow: /):
curl -s 'https://chat.mistral.ai/robots.txt' | sed -n '1,2p'
xAI → OpenAI, Anthropic, Amazon and Common CrawlAn edge rule on grok.com refuses GPTBot, ClaudeBot, Amazonbot and CCBot - every one of those names gets the edge’s block response.Show evidence (3 commands)
GPTBot refused by the edge rule - expect HTTP 403:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot' 'https://grok.com/'
ClaudeBot refused by the edge rule - expect HTTP 403:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; ClaudeBot/1.0; [email protected])' 'https://grok.com/'
CCBot refused by the edge rule - expect HTTP 403:
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://grok.com/'
“AI companies rely on an open web to power their products, but our research shows that seven are actively blocking competitors by name. You can’t champion an open web, whilst closing the door on your rivals.”
Matthew Woodward, founder, LinksThatRank
Why this is newsworthy
The companies whose products depend on crawling the open web are the only ones in the industry closing it to each other.
A cell shows the worst verdict across all of a company’s tested sites. “Not verified” is an inference from Cloudflare’s published verified-bot list, not an observed rule - see the methodology.
Perplexity runs the most blocked AI search crawler - and blocks OpenAI, Anthropic and Meta itself.
PerplexityBot is refused on 15 of the 115 sites tested: six by a rule that names it, nine more because those sites’ Cloudflare bot protection admits only crawlers on Cloudflare’s verified list, which Perplexity’s is not (an inference from that list - see the method). In the other direction, perplexity.ai refuses four rivals’ crawlers by name with HTTP 403 from both vantage points.
Context: only the training crawlers (CCBot and the image and data-set bots) are shut out of more sites - and those are opt-outs from model training, not from search (see the crawlers shut out most).
Why this is newsworthy
Both directions at once: the industry shuts Perplexity’s crawler out more than any other search bot, and Perplexity shuts out OpenAI, Anthropic, Meta and You.com by name.
Most of the AI industry is open. The apps are where the blocking happens.
78 of the 99 corporate websites answered every one of the 33 crawler identities with the page. The strictness is in the product domains: 6 of the 16 apps tested block a rival by name - chatgpt.com, claude.ai, ai.meta.com, meta.ai, chat.mistral.ai and grok.com - against 10 of the 99 corporate sites. The pattern is consistent: the marketing site stays open, the app that holds the conversations does not.
Cloudflare’s verified-bot list decides which AI crawlers get into 11 of the sites.
Seven corporate sites and four product domains run Cloudflare bot protection that challenges every crawler it cannot verify. Crawlers on Cloudflare’s published list get through - OAI-SearchBot, ClaudeBot, Amazonbot, DuckAssistBot and the rest. The ones not on it, Google-GeminiNotebook, Perplexity-User, PerplexityBot among them, get the same challenge our test did.
The crawlers shut out most
Sites turning each crawler away across all 115, by name or as not Cloudflare-verified (inferred) · top 12.
CCBot Common Crawl18
ImagesiftBot Imagesift15
PerplexityBot Perplexity15
AI2Bot Allen Institute for AI (Ai2)14
Timpibot Timpi14
Google-GeminiNotebook Google14
Diffbot Diffbot13
MistralAI-Training Mistral AI12
webzio Webz.io12
GPTBot OpenAI11
Amzn-User Amazon10
Perplexity-User Perplexity10
Blocked by nameRefused as not Cloudflare-verified (inferred)
Read the floor, not the ceiling: training crawlers are sent last in each check and time out first on slow sites, so their counts are a floor.
Who fronts the 99 corporate sites
43/99
Cloudflare
22/99
Vercel
11/99
No CDN / WAF detected
6/99
AWS CloudFront / WAF
5/99
Google Cloud
5/99
Origin (nginx)
2/99
Akamai
2/99
Origin (Apache)
1/99
Azure Front Door
1/99
Squarespace / Fastly each
Why this is newsworthy
Whether a new AI crawler can read the AI industry’s own websites increasingly comes down to one vendor’s verified-bot list.
“Not verified” verdicts are an inference from Cloudflare’s published list; the observed fact is that the site challenged our copy of the crawler and a spoofed Googlebot alike.
45 of 99 AI companies publish an llms.txt. None of the eight largest does.
The industry adopts the machine-readability standard it asks of everyone else - up to a point. Nine more companies answer the llms.txt URL with an HTML page or an error instead of the file, and not one of the 99 publishes a valid TDM reservation file (tdmrep.json).
45
Publish a valid llms.txt45% of the 99 corporate sites serve a file that parses as llms.txt.
9
Answer the URL with something elseAn HTML page or an error where the file should be.
0
Of the eight largest have oneOpenAI, Anthropic, Google, Microsoft, Meta, Amazon, Apple, Perplexity.
0
Publish a valid tdmrep.jsonNo company serves a valid TDM reservation file.
Among the adopters:
Google DeepMindMistral AIYou.comDiffbotHive (ImageSift)CohereDatabricksCrusoeSambaNovaTogether AIBasetenFireworks AI+ 33 more
Why this is newsworthy
The AI ecosystem’s own machine-readability standard has 45% adoption among AI companies - and zero among the eight biggest.
Valid llms.txt45 of 99
Of the eight largest0 of 8
Valid tdmrep.json0 of 99
6
The robots.txt layer
Training opt-outs are small, and the robots.txt files still block crawlers that no longer exist.
Eleven of the 99 corporate sites restrict the crawlers that collect training data - seven in robots.txt, four with an edge rule only (Microsoft, Perplexity, Tencent and Writer) - and training policies never count against a company in this report. Meanwhile five sites still carry rules for retired crawler names that match nothing, and six allow a crawler in robots.txt that their edge then refuses by name.
11
Restrict training crawlersGPTBot, ClaudeBot, CCBot, meta-externalagent, Amazonbot and the rest - 7 in robots.txt, 4 at the edge only.
3
Block all five big training botsThe only sites restricting every major training crawler at once.
5
Carry retired crawler nameschatgpt.com, amazon.com, reflection.ai, midjourney.com and 1 more disallow names like anthropic-ai, Claude-Web, Omgilibot, Omgili - rules that match nothing today. more
6
robots.txt says allow, edge says noThe file allows a crawler the edge refuses by name - invisible to a robots-only audit.
6
Name any AI crawler in robots.txtOnly six of the 99 corporate sites mention one at all.
Why this is newsworthy
A robots.txt-only audit of the AI industry reads rules that match nothing - and misses the blocks that live at the edge.
Sites with retired crawler names5
robots.txt allow vs edge refusal6
Corporate robots.txt naming any AI crawler6 of 99
Group by group
Every group is around three-quarters open - the blocking sits with the crawler operators themselves.
The 99 companies in three groups: the 21 whose crawlers this test sends, the Forbes AI 50 of 2026, and other notable labs and AI-first companies.
76% fully open - 16 open, 1 verified crawlers only, 1 training only, 1 blocks AI assistants, 1 blocks AI search, 1 robots.txt blocks AI search.
The twist: the most open group contains every one of the industry’s by-name blockers.
Forbes AI 50 (2026) 47 companies
77% fully open - 36 open, 1 bot management, 5 verified crawlers only, 2 training only, 1 challenged, 2 robots.txt blocks AI search.
Pattern: the challenges here are Vercel and Cloudflare defaults, not AI policies.
Other notable AI companies 31 companies
84% fully open - 26 open, 1 verified crawlers only, 1 blocks AI assistants, 1 blocks AI search, 2 robots.txt blocks AI search.
Every company
All 99 AI companies, ranked by what they block.
All 115 tested sites: the answer to AI crawlers, what each blocks by name, the blocking layer, the training policy and llms.txt, with the per-crawler verdicts behind every row. Product domains sit under their company’s corporate site.
Ordered by what each company blocks: the companies that name a rival’s crawler in a rule first, then the sites that admit only Cloudflare-verified crawlers, the training-only opt-outs, the bot defences, and the open ones. Click a column to sort, use the filter to narrow the list, and open a row for the crawler-by-crawler verdicts. 16 product domains (the apps: chatgpt.com, claude.ai, meta.ai …) are marked product under their company’s corporate site (↳). Each row has its own link (the # beside the name). Download the CSV.
Cloudflare blocks bot traffic it does not recognise. An unknown, self-identifying bot got the same HTTP 403 as 7 AI crawlers, so this is bot management, not a rule naming them.
Show evidence (6 commands: every verdict other than a plain allow)
PerplexityBot · Blocked by name · HTTP 403 · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://writer.com/'
YouBot · Blocked by name · HTTP 403 · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; YouBot/1.0; +https://docs.you.com/youbot; env:prod) Chrome/X.X.X.X Safari/537.36' 'https://writer.com/'
GPTBot · Blocked by name · HTTP 403 · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot' 'https://writer.com/'
ClaudeBot · Blocked by name · HTTP 403 · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; ClaudeBot/1.0; [email protected])' 'https://writer.com/'
CCBot · Blocked by name · HTTP 403 · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://writer.com/'
Amazonbot · Blocked by name · HTTP 403 · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Amazonbot/0.1) Chrome/W.X.Y.Z Safari/537.36' 'https://writer.com/'
Robots.txt disallows 10 AI search crawlers and assistants (OAI-SearchBot, Claude-SearchBot, PerplexityBot, meta-webindexer and 6 more); behind it, Akamai also keeps 5 more from the page (5 challenged: Applebot, Perplexity-User, Amzn-User, Google-Agent and 1 more).
Cloudflare's bot protection lets verified crawlers in (Claude, Google, Bing, Apple and 5 more), but PerplexityBot, Perplexity-User, Amzn-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · AI tokens in robots.txt: GPTBot, OAI-SearchBot, ChatGPT-User, Google-Extended · llms.txt present · checked 6 November 2026
OAI-SearchBot robots.txtClaude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot Allowed (verified)MistralAI-Index Allowed (verified)DuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User robots.txtClaude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User Not verifiedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot robots.txtClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training Not verifiedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot Not verifiedTimpibot Not verifiedwebzio Not verifiedImagesiftBot Not verifiedKagibot Allowed (verified)GoogleOther Allowed (verified)Google-Extended robots.txtApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (4 commands: every verdict other than a plain allow)
OAI-SearchBot · Disallowed in robots.txt · line 10: Disallow: / · robots.txt:
curl -s 'https://claude.ai/robots.txt' | sed -n '6,10p'
ChatGPT-User · Disallowed in robots.txt · line 10: Disallow: / · robots.txt:
curl -s 'https://claude.ai/robots.txt' | sed -n '6,10p'
GPTBot · Disallowed in robots.txt · line 10: Disallow: / · robots.txt:
curl -s 'https://claude.ai/robots.txt' | sed -n '6,10p'
Claude-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Claude-SearchBot/1.0; [email protected])' 'https://claude.ai/login'
The site lets 5 crawler user agents through (Googlebot, bingbot, Applebot, Google-CloudVertexBot and 1 more) and refuses every other automated client, our honest bot included: even a browser gets HTTP 403. 3 AI search crawlers and assistants are not on that list and get the same HTTP 403 (Perplexity-User, Google-Agent and Google-GeminiNotebook).
Tested from 2 vantage points (2 usable) · robots.txt readable · AI tokens in robots.txt: Amazonbot, Applebot-Extended, ClaudeBot, Google-Extended, GPTBot, PerplexityBot · checked 6 November 2026
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Bing and 5 more), but PerplexityBot, Perplexity-User, Amzn-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot Allowed (verified)MistralAI-Index Allowed (verified)DuckAssistBot Allowed (verified)YouBot robots.txtGooglebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User Not verifiedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot robots.txtClaudeBot Allowed (verified)CCBot robots.txtmeta-externalagent robots.txtAmazonbot robots.txtMistralAI-Training Not verifiedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot robots.txtTimpibot Not verifiedwebzio Not verifiedImagesiftBot robots.txtKagibot Allowed (verified)GoogleOther Allowed (verified)Google-Extended robots.txtApplebot-Extended robots.txtwebzio-extended AllowedCoherebot Allowed
Show evidence (8 commands: every verdict other than a plain allow)
YouBot · Disallowed in robots.txt · line 97: Disallow: / · robots.txt:
curl -s 'https://midjourney.com/robots.txt' | sed -n '96,97p'
GPTBot · Disallowed in robots.txt · line 55: Disallow: / · robots.txt:
curl -s 'https://midjourney.com/robots.txt' | sed -n '54,55p'
CCBot · Disallowed in robots.txt · line 58: Disallow: / · robots.txt:
curl -s 'https://midjourney.com/robots.txt' | sed -n '57,58p'
meta-externalagent · Disallowed in robots.txt · line 112: Disallow: / · robots.txt:
curl -s 'https://midjourney.com/robots.txt' | sed -n '111,112p'
Amazonbot · Disallowed in robots.txt · line 93: Disallow: / · robots.txt:
curl -s 'https://midjourney.com/robots.txt' | sed -n '92,93p'
Diffbot · Disallowed in robots.txt · line 70: Disallow: / · robots.txt:
curl -s 'https://midjourney.com/robots.txt' | sed -n '69,70p'
ImagesiftBot · Disallowed in robots.txt · line 79: Disallow: / · robots.txt:
curl -s 'https://midjourney.com/robots.txt' | sed -n '78,79p'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · line 138: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://www.midjourney.com/'
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Bing and 6 more), but PerplexityBot, Perplexity-User, Amzn-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · checked 6 November 2026
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot Allowed (verified)MistralAI-Index AllowedDuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User Not verifiedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot Allowed (verified)ClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training Not verifiedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot Not verifiedTimpibot Not verifiedwebzio Not verifiedImagesiftBot Not verifiedKagibot AllowedGoogleOther Allowed (verified)Google-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (4 commands: every verdict other than a plain allow)
PerplexityBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://openai.com/'
Perplexity-User · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)' 'https://openai.com/'
CCBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://openai.com/'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · line 2: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://openai.com/'
Robots.txt disallows 14 AI search crawlers and assistants (OAI-SearchBot, Claude-SearchBot, PerplexityBot, meta-webindexer and 10 more). Behind it, Cloudflare's bot protection lets verified crawlers in but locks out Perplexity-User and Google-GeminiNotebook (not Cloudflare-verified).
Tested from 2 vantage points (2 usable) · robots.txt readable · llms.txt present · checked 6 November 2026
No AI search crawler or assistant is blocked. webzio and GoogleOther (training crawlers) got a different page (HTTP 200): a policy choice that costs no AI search visibility.
Tested from 2 vantage points (2 usable) · robots.txt readable · silent blocks: webzio, GoogleOther · checked 6 November 2026
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Apple and 5 more), but PerplexityBot, Perplexity-User, Amzn-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · AI tokens in robots.txt: GPTBot, Google-Extended · llms.txt present · checked 6 November 2026
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot Allowed (verified)MistralAI-Index Allowed (verified)DuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User Not verifiedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot robots.txtClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training Not verifiedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot Not verifiedTimpibot Not verifiedwebzio Not verifiedImagesiftBot Not verifiedKagibot Allowed (verified)GoogleOther Allowed (verified)Google-Extended robots.txtApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (5 commands: every verdict other than a plain allow)
GPTBot · Disallowed in robots.txt · line 2: Disallow: / · robots.txt:
curl -s 'https://chat.mistral.ai/robots.txt' | sed -n '1,2p'
PerplexityBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://chat.mistral.ai/chat'
Perplexity-User · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)' 'https://chat.mistral.ai/chat'
CCBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://chat.mistral.ai/chat'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://chat.mistral.ai/chat'
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Bing and 5 more), but PerplexityBot, Perplexity-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same refusal as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · checked 6 November 2026
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot AllowedMistralAI-Index AllowedDuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User AllowedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot Allowed (verified)ClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training AllowedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot AllowedTimpibot Not verifiedwebzio AllowedImagesiftBot Not verifiedKagibot AllowedGoogleOther Allowed (verified)Google-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (4 commands: every verdict other than a plain allow)
PerplexityBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · title "Attention Required! | Cloudflare":
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://x.ai/'
Perplexity-User · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · title "Attention Required! | Cloudflare":
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)' 'https://x.ai/'
CCBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · title "Attention Required! | Cloudflare":
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://x.ai/'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · line 2: Allow: / · title "Attention Required! | Cloudflare":
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://x.ai/'
Cloudflare blocks 4 AI training crawlers at the edge (GPTBot, ClaudeBot, CCBot and Amazonbot): a policy choice that keeps content out of model training. No AI search crawler or assistant is blocked.
Tested from 2 vantage points (2 usable) · robots.txt readable · AI tokens in robots.txt: GPTBot, ChatGPT-User, PerplexityBot, ClaudeBot, Google-Extended, Applebot-Extended · silent blocks: GPTBot, ClaudeBot, CCBot, Amazonbot · checked 6 November 2026
Show evidence (4 commands: every verdict other than a plain allow)
GPTBot · Blocked by name · HTTP 403 · line 20: Allow: /$ · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko); compatible; GPTBot/1.4; +https://openai.com/gptbot' 'https://grok.com/'
ClaudeBot · Blocked by name · HTTP 403 · line 20: Allow: /$ · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; ClaudeBot/1.0; [email protected])' 'https://grok.com/'
CCBot · Blocked by name · HTTP 403 · line 2: Allow: / · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://grok.com/'
Amazonbot · Blocked by name · HTTP 403 · line 2: Allow: / · body: "Your request was blocked." (text/plain — Cloudflare AI Crawl Control policy response):
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Amazonbot/0.1) Chrome/W.X.Y.Z Safari/537.36' 'https://grok.com/'
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Bing and 6 more), but PerplexityBot, Perplexity-User, Amzn-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · checked 6 November 2026
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot Allowed (verified)MistralAI-Index Allowed (verified)DuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User Not verifiedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot Allowed (verified)ClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training Not verifiedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot Not verifiedTimpibot Not verifiedwebzio Not verifiedImagesiftBot Not verifiedKagibot Allowed (verified)GoogleOther Allowed (verified)Google-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (4 commands: every verdict other than a plain allow)
PerplexityBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · title "Attention Required! | Cloudflare":
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://character.ai/'
Perplexity-User · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · title "Attention Required! | Cloudflare":
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)' 'https://character.ai/'
CCBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · title "Attention Required! | Cloudflare":
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://character.ai/'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · title "Attention Required! | Cloudflare":
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://character.ai/'
Cloudflare's bot protection lets verified crawlers in (Google, Bing), but Google-GeminiNotebook is not on Cloudflare's verified list, so it gets the same refusal as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · llms.txt valid · checked 6 November 2026
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Bing and 6 more), but PerplexityBot, Perplexity-User, Amzn-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · llms.txt valid · checked 6 November 2026
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot Allowed (verified)MistralAI-Index Allowed (verified)DuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User Not verifiedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot Allowed (verified)ClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training Not verifiedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot Not verifiedTimpibot Not verifiedwebzio Not verifiedImagesiftBot Not verifiedKagibot Allowed (verified)GoogleOther Allowed (verified)Google-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (4 commands: every verdict other than a plain allow)
PerplexityBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://gamma.app/'
Perplexity-User · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)' 'https://gamma.app/'
CCBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://gamma.app/'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · line 14: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://gamma.app/'
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Bing and 5 more), but PerplexityBot, Perplexity-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · llms.txt valid · checked 6 November 2026
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot AllowedMistralAI-Index AllowedDuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User AllowedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot Allowed (verified)ClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training AllowedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot AllowedTimpibot Not verifiedwebzio AllowedImagesiftBot Not verifiedKagibot AllowedGoogleOther Allowed (verified)Google-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (4 commands: every verdict other than a plain allow)
PerplexityBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://www.genspark.ai/'
Perplexity-User · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)' 'https://www.genspark.ai/'
CCBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://www.genspark.ai/'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://www.genspark.ai/'
Cloudflare's bot protection lets verified crawlers in (ChatGPT, Claude, Google, Bing and 6 more), but PerplexityBot, Perplexity-User, Amzn-User and Google-GeminiNotebook are not on Cloudflare's verified list, so they get the same challenge as our test and can't read the site.
Tested from 2 vantage points (2 usable) · robots.txt readable · llms.txt valid · checked 6 November 2026
OAI-SearchBot Allowed (verified)Claude-SearchBot Allowed (verified)PerplexityBot Not verifiedmeta-webindexer Allowed (verified)Amzn-SearchBot Allowed (verified)MistralAI-Index Allowed (verified)DuckAssistBot Allowed (verified)YouBot Allowed (verified)Googlebot Allowed (verified)bingbot Allowed (verified)Applebot Allowed (verified)ChatGPT-User Allowed (verified)Claude-User Allowed (verified)Perplexity-User Not verifiedmeta-externalfetcher Allowed (verified)MistralAI-User Allowed (verified)Amzn-User Not verifiedGoogle-Agent Allowed (verified)Google-GeminiNotebook Not verifiedGPTBot Allowed (verified)ClaudeBot Allowed (verified)CCBot Not verifiedmeta-externalagent Allowed (verified)Amazonbot Allowed (verified)MistralAI-Training Not verifiedAI2Bot Not verifiedGoogle-CloudVertexBot Allowed (verified)Diffbot Not verifiedTimpibot Not verifiedwebzio Not verifiedImagesiftBot Not verifiedKagibot Allowed (verified)GoogleOther Allowed (verified)Google-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Show evidence (4 commands: every verdict other than a plain allow)
PerplexityBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 56: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; PerplexityBot/1.0; +https://perplexity.ai/perplexitybot)' 'https://lovable.dev/'
Perplexity-User · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)' 'https://lovable.dev/'
CCBot · Refused: not on Cloudflare's verified list (inferred) · HTTP 403 · line 2: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'CCBot/2.0 (https://commoncrawl.org/faq/)' 'https://lovable.dev/'
OAI-SearchBot · Allowed as a verified crawler (inferred) · HTTP 403 · line 56: Allow: / · cf-mitigated: challenge:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://lovable.dev/'
No AI crawler is blocked. AWS CloudFront / WAF serves every tested user agent the same page as a browser.
Tested from 2 vantage points (1 usable) · robots.txt readable · checked 6 November 2026
OAI-SearchBot AllowedClaude-SearchBot AllowedPerplexityBot Allowedmeta-webindexer AllowedAmzn-SearchBot AllowedMistralAI-Index AllowedDuckAssistBot AllowedYouBot AllowedGooglebot Allowedbingbot AllowedApplebot Not testedChatGPT-User Not testedClaude-User Not testedPerplexity-User Not testedmeta-externalfetcher Not testedMistralAI-User Not testedAmzn-User Not testedGoogle-Agent Not testedGoogle-GeminiNotebook Not testedGPTBot Not testedClaudeBot Not testedCCBot Not testedmeta-externalagent Not testedAmazonbot Not testedMistralAI-Training Not testedAI2Bot Not testedGoogle-CloudVertexBot Not testedDiffbot Not testedTimpibot Not testedwebzio Not testedImagesiftBot Not testedKagibot Not testedGoogleOther Not testedGoogle-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
AWS CloudFront / WAF refuses requests that claim a known crawler identity without verifying it. A spoofed Googlebot or bingbot is blocked the same way, so it is checking who crawlers are, not blocking AI by name.
Tested from 2 vantage points (1 usable) · robots.txt unreadable challenge · checked 6 November 2026
Show evidence (8 commands: every verdict other than a plain allow)
OAI-SearchBot · Refused as unverified · HTTP 403 · http 403:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://chat.deepseek.com/'
Vercel refuses non-browser clients generally. Our honest, self-identifying control got the same HTTP 403 as 33 AI crawlers while a browser passes, so this is bot management, not a rule naming them.
Tested from 2 vantage points (2 usable) · robots.txt readable · checked 6 November 2026
Show evidence (8 commands: every verdict other than a plain allow)
OAI-SearchBot · Refused as unrecognised bot · HTTP 403 · x-vercel-mitigated: deny:
curl -sSI -A 'Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/131.0.0.0 Safari/537.36; compatible; OAI-SearchBot/1.4; +https://openai.com/searchbot' 'https://www.openevidence.com/'
Cloudflare's bot protection lets verified crawlers in (Google, Bing); it only refuses unverified copies like our test, so it costs you no AI visibility.
Tested from 2 vantage points (2 usable) · robots.txt readable · llms.txt valid · checked 6 November 2026
No AI crawler is blocked. AWS CloudFront / WAF serves every tested user agent the same page as a browser.
Tested from 2 vantage points (2 usable) · robots.txt readable · checked 6 November 2026
OAI-SearchBot AllowedClaude-SearchBot AllowedPerplexityBot Allowedmeta-webindexer AllowedAmzn-SearchBot AllowedMistralAI-Index AllowedDuckAssistBot AllowedYouBot AllowedGooglebot Allowedbingbot AllowedApplebot AllowedChatGPT-User AllowedClaude-User AllowedPerplexity-User Allowedmeta-externalfetcher AllowedMistralAI-User AllowedAmzn-User AllowedGoogle-Agent Not testedGoogle-GeminiNotebook Not testedGPTBot Not testedClaudeBot Not testedCCBot Not testedmeta-externalagent Not testedAmazonbot Not testedMistralAI-Training Not testedAI2Bot Not testedGoogle-CloudVertexBot Not testedDiffbot Not testedTimpibot Not testedwebzio Not testedImagesiftBot Not testedKagibot Not testedGoogleOther Not testedGoogle-Extended AllowedApplebot-Extended Allowedwebzio-extended AllowedCoherebot Allowed
Showing the first 3 companies. Filtering, sorting or a row link opens the whole table.
Would your site pass the same test?
Paste your domain into the free AI Visibility Checker: it runs the same 33-crawler test, names the layer that blocks each crawler and gives you the fix.
Everything on this page may be quoted and reused with credit under CC BY 4.0. The dataset, charts and per-company breakdowns are free to download, and press requests get a same-day answer.
Full CSV115 sites · one row each · every verdict plus the robots.txt and llms.txt findings · 12 borderline big-tech rows marked as not counted
Download CSV
Publication chartsWho blocks whom · The Perplexity problem · How the sites answer AI crawlers · The crawlers shut out most · Group by group
Bespoke cutsCompany, group and crawler breakdowns, plus the raw request logs behind any verdict, on request
Interview / commentPress requests answered the same working day: [email protected]
Paste this where the chart should appear. It links back to the report; the source line is part of the image.
Cite as:LinksThatRank, AI Companies AI Visibility Report, November 2026, https://linksthatrank.com/ai-visibility-checker/which-ai-companies-block-ai-crawlers/
Methodology
How we tested: 99 companies, 115 sites, 33 crawler identities, two vantage points.
Everything a reporter, editor or technical reader needs to check exactly how each classification was made. The full method is on the methodology page.
Who99 AI companies in three groups as of 19 October 2026: the 21 companies whose crawlers the test sends, the Forbes AI 50 of 2026, and other notable labs and AI-first companies. Official websites came from Wikidata (P856) and were checked by hand. Where a consumer product lives on another domain (chatgpt.com, claude.ai, meta.ai, grok.com and 12 more), that domain was tested too and reported as a product domain; the corporate site is the one classified and counted. Twelve borderline big-tech companies are in the CSV marked as not counted and are left out of every number on this page.
WhatThe AI Visibility Checker engine, unchanged: robots.txt, the homepage and one deeper page fetched as a browser with a real Chrome TLS fingerprint, an honest self-identifying bot, a never-seen bot invented for the test, and 33 exact AI-crawler user agents, plus llms.txt and tdmrep.json. Verdicts are per crawler, with the blocking layer named from the response signature (Cloudflare block page, challenge or AI Crawl Control response; Vercel challenge; AWS WAF; Akamai; Imperva).
From whereTwo vantage points: our data-centre addresses (DigitalOcean London and Vultr New Jersey); US and UK ISP addresses (static residential-grade, Bright Data). A crawler counts as blocked by name only when a testable vantage saw the rule and no vantage saw the same crawler allowed; a block from one vantage and an allow from the other is recorded as inconsistent and not counted. No residential pass was run for this study.
Verification, inference and blockingA site that refuses a spoofed Googlebot and bingbot the same way it refuses a spoofed AI crawler is checking identity, not blocking AI. On Cloudflare that check is the verified-bot list: a crawler on the list is reported as allowed (verified) and one that is not as refused, not verified - both labelled as an inference from Cloudflare’s published list, because our requests are unverified by construction. A site that refuses our invented bot the same way is classed as bot management. Only a rule that names the crawler, in robots.txt or at the edge, is reported as “blocks by name”.
robots.txtRead as RFC 9309: a group’s most specific user-agent match wins and a * group applies to crawlers not named, with the rule and its line number recorded for every disallow. Retired crawler names (anthropic-ai, Claude-Web, FacebookBot, Omgili) are reported as such: they match no current crawler. Google-Extended and Applebot-Extended are robots.txt-only opt-out tokens, read from the file and never sent as user agents.
The checker’s scoreThe free checker scores each site from a single vantage point; this report classifies each site by the agreement of two, so the two can differ. The score is not shown here and appears in the CSV as checker_score_best_vantage for reference only.
What we cannot knowWhat a site’s own allow list contains beyond what Cloudflare publishes; whether a block is a decision about that crawler or a side effect of a copied “block AI bots” list (the retired names suggest some are); and anything about sites that could not be tested from either vantage point, reported as untested rather than guessed. Results are a snapshot of 6–7 November 2026; the study is re-run quarterly (next: February 2027) and the changes published.
Why “not on Cloudflare’s verified list” is an inference, not an observed block
The test requests deliberately claimed crawler identities without the private network or verification signals authentic crawlers can provide. On a site running Cloudflare’s verified-bot gate, the observed fact is that our copy of the crawler and a spoofed Googlebot got the same challenge. The verdict for crawlers not on Cloudflare’s published list follows from that list, and the report labels it as an inference everywhere it appears.
Why a bot-defence verdict is not the same as “blocks AI”
When a site also refuses our invented, never-seen bot the same way it refuses an AI crawler, the evidence points to generic bot management rather than an AI-specific policy. Only a rule that names the crawler - in robots.txt or at the edge - is reported as a block, and training-crawler restrictions never count against a company in this report.


 Google
 Google DeepMind
 Apple
 You.com
 DuckDuckGo
 Common Crawl
 Ai2 (Allen Institute)
 Diffbot
 Kagi
 Timpi
 Hive (ImageSift)
 Webz.io
 Brave
 Cohere

 chatgpt.com
 meta.ai
 baidu.com
 writer.com
 poe.com
 claude.ai
 chat.mistral.ai
 genspark.ai
 gamma.app
 midjourney.com
 lovable.dev
 character.ai


 Databricks
 Crusoe
 SambaNova
 Together AI
 Baseten
 Fireworks AI